Cron, Clocks and the Missing Hour: Scheduling Loaders for Europe/London
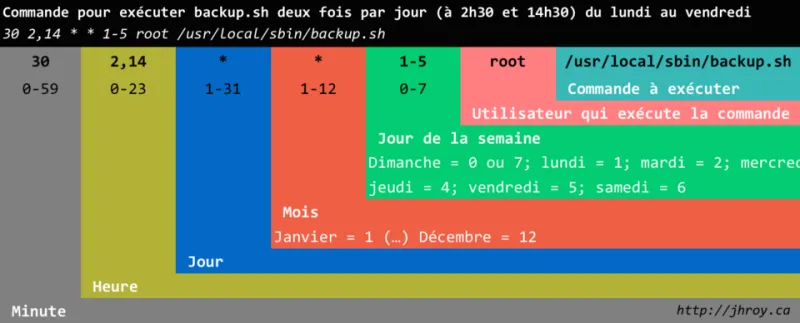
Photo: Groov3, CC BY-SA 4.0, via Wikimedia Commons
The clocks went back in the UK on 25 October 2026. If your scheduled loaders are still running on server local time, that quiet Sunday was probably fine. The next one may not be. Daylight-saving transitions are a twice-yearly reminder that cron expressions are not timezone-aware in the way most of us assume.
The problem is not complicated. It is just easy to ignore until a nightly import runs twice, a report lands in the wrong hour, or a loader skips a run entirely because 01:30 did not exist. In the UK, we move between Greenwich Mean Time and British Summer Time. The switch happens at 01:00 local time. In spring, 01:00 to 01:59 vanishes. In autumn, 01:00 to 01:59 happens twice. Any job scheduled in that window is asking for trouble.
Why 0 1 * * * is a lie twice a year
A cron entry like 0 1 * * * looks precise. It means one o'clock in the morning to the daemon reading it. If that daemon uses the host timezone, and the host timezone is Europe/London, then one o'clock is not always a single moment. On the spring transition, it does not exist. On the autumn transition, it exists twice. Different cron implementations handle this differently: some skip, some run twice, some run once at the first or second occurrence. None of that is a business rule you chose.
The same trap appears in Kubernetes CronJobs, systemd timers, cloud schedulers, and the little Python script that someone attached to a queue. Containers often default to UTC, which is safer, but then a job meant for 07:00 London time drifts by an hour in summer. That is fine for an interval job and not fine for a report that staff expect before the morning stand-up.
Decide what the schedule actually means
Before you write code, decide whether the job is tied to elapsed time or wall-clock time. An interval job, such as refreshing a cache every 15 minutes, should run in UTC. A business job, such as importing a supplier file at 06:00 London time, should be expressed as a local wall time and resolved to UTC for execution. Mixing the two is where the bugs live.
Store schedule definitions with an explicit timezone. Do not store a fixed offset like +01:00. London is not always +01:00. Use Europe/London and let the timezone database do the work. In Python, zoneinfo is enough for most teams:
from datetime import datetime, time
from zoneinfo import ZoneInfo
LONDON = ZoneInfo('Europe/London')
UTC = ZoneInfo('UTC')
Then resolve a local wall time to an instant. The important part is handling the two awkward cases: nonexistent times and ambiguous times.
A small utility that refuses to guess
Here is a compact approach. It checks whether a local time exists, detects ambiguity, and lets the caller choose a fold when the clock goes back. The fold value tells Python which of the two possible offsets to use: 0 for the first occurrence, 1 for the second.
from datetime import datetime
from zoneinfo import ZoneInfo
LONDON = ZoneInfo('Europe/London')
UTC = ZoneInfo('UTC')

def london_offsets(naive):
    first = naive.replace(tzinfo=LONDON, fold=0).utcoffset()
    second = naive.replace(tzinfo=LONDON, fold=1).utcoffset()
    return first, second

def resolve_london(naive, fold=0):
    first, second = london_offsets(naive)
    local = naive.replace(tzinfo=LONDON, fold=fold)
    utc = local.astimezone(UTC)
    roundtrip = utc.astimezone(LONDON).replace(tzinfo=None)
    if roundtrip != naive:
        raise ValueError(f'Nonexistent London time: {naive}')
    if first != second and fold not in (0, 1):
        raise ValueError(f'Ambiguous London time: {naive}')
    return utc
Call resolve_london(datetime(2026, 3, 29, 1, 30)) and it raises, because that time never happens. Call it for 25 October 2026 at 01:30 and it returns the first occurrence unless you pass fold=1. The job then logs both the local intent and the UTC instant. That log line is worth its weight in gold when someone asks why the import ran at the wrong time.
Test the transitions, not just a Tuesday
Write tests for the two Sundays, not for a random day in June. For 2026, the UK transitions were 29 March and 25 October. A useful test set looks like this:
- 00:30 on a normal day resolves to the expected UTC offset.
- 01:30 on the spring transition raises or is rejected by the scheduler.
- 01:30 on the autumn transition resolves to two distinct UTC instants.
- 02:30 after each transition resolves normally.
- A daily 06:00 London job produces 05:00 UTC in summer and 06:00 UTC in winter.
If you use pytest, parametrise the cases and assert on UTC, not on local strings. Local strings are for humans. UTC is for comparisons.
Make the scheduler boring
A few rules keep scheduled loaders predictable. Run cron in UTC where you can, and convert business schedules at the edge. Set TZ=UTC in containers so a stray library does not pick up the host timezone. Avoid scheduling critical jobs between 00:30 and 02:30 on transition days unless you have a specific reason. Make every loader idempotent, with a unique key or a run ledger, so a double execution does not double-charge a customer or duplicate a row. Log the resolved UTC time, the local time, and the timezone name. If a job can be delayed, give it a window rather than a single minute.
The hour you do not lose
The UK clock change is not exotic. It is a known event with a known date, and yet it still catches teams because the bug is invisible for 364 days. Treat timezone handling as part of the loader, not as a deployment detail. Resolve local times explicitly, test both transitions, and make the scheduler say what it means. Then the only thing that changes twice a year is the clock on the wall, not your overnight imports.